
Most machine-learning stories celebrate confidence. Stanford’s antimicrobial polymer work is more interesting because the researchers deliberately looked for places where the models were unsure.
The mechanism
Antimicrobial peptides can damage bacterial membranes physically, a mechanism that may be harder for bacteria to evade than a drug aimed at one narrow biochemical pathway. Peptides, however, can be expensive to make and degrade quickly.
The Stanford team searched for polymers that could reproduce useful antimicrobial characteristics while being cheaper and more durable. The problem was data. Large datasets exist for peptides; comparable polymer data are scarce.
The researchers first trained on antimicrobial peptide properties, then transferred that information into models used to score a library of roughly 1.7 million potential polymers.
Why it matters
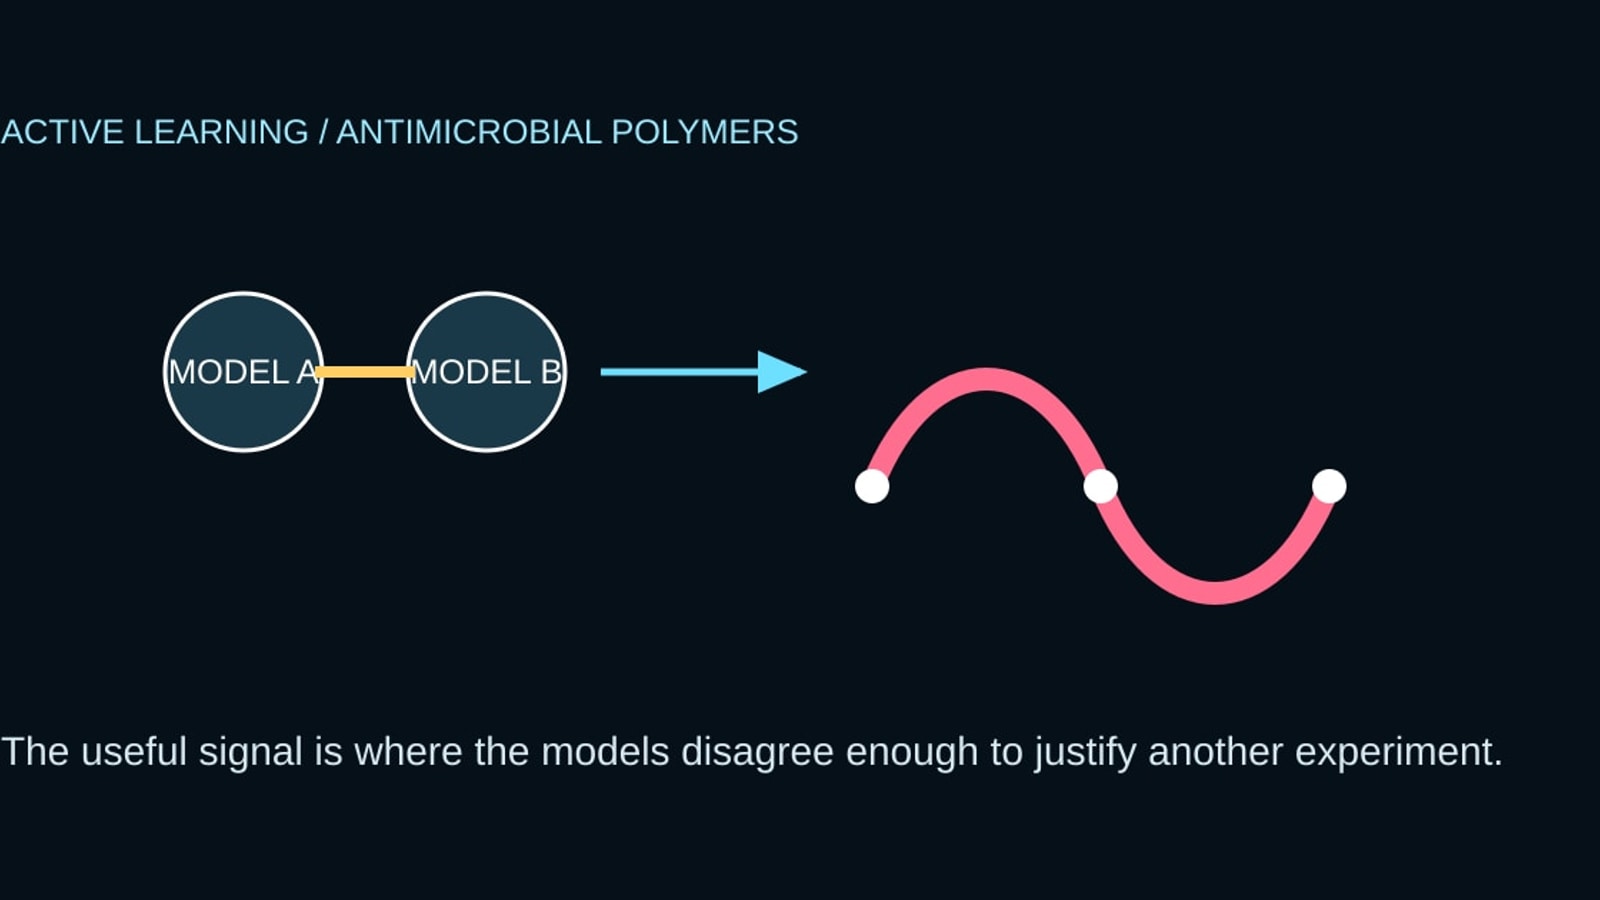
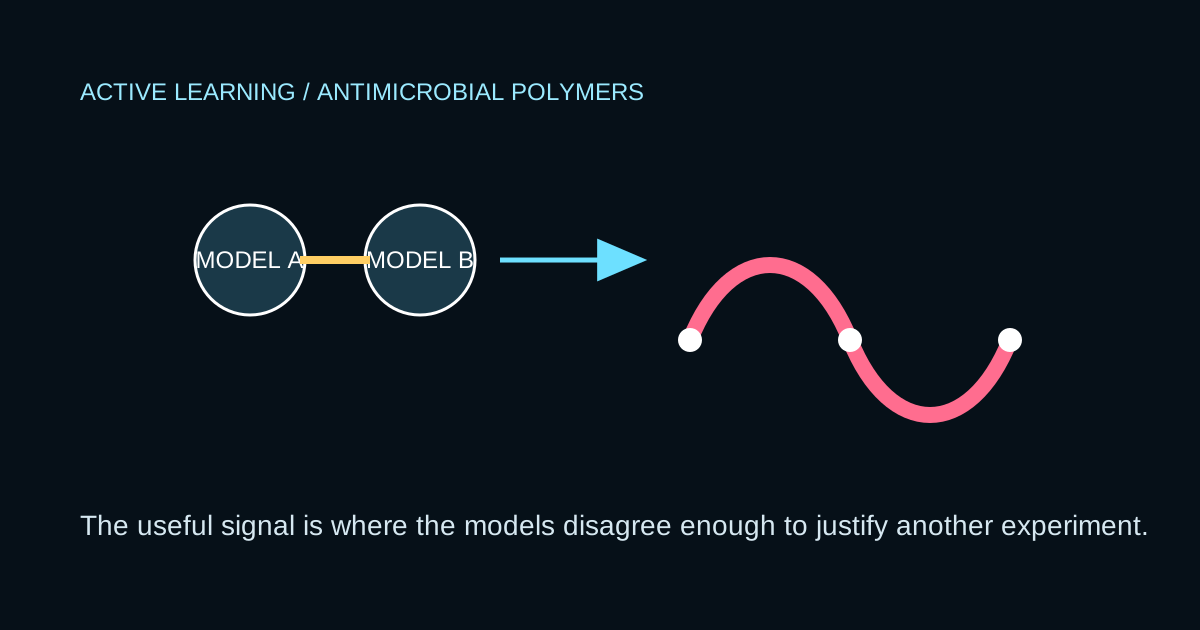
Instead of testing only the molecules the models liked most, the team synthesized candidates where different models disagreed sharply. Those experiments produced new information precisely in the regions where the prediction system was weakest. Feeding that data back improved the search.
With the refined tool, the team selected ten polymer candidates for antimicrobial testing. Stanford reports that all ten exceeded expectations against E. coli, with one showing particular effectiveness against biofilms.
Evidence boundary
What remains unknown: the reported results are laboratory findings, not evidence of a new approved antibiotic class. Safety in humans, dosing, resistance under prolonged exposure, manufacturing and performance against clinical infections remain to be established.
the clever part is not that AI ranked molecules. It is that uncertainty was promoted from an embarrassment in the model output to a steering signal for the laboratory.