
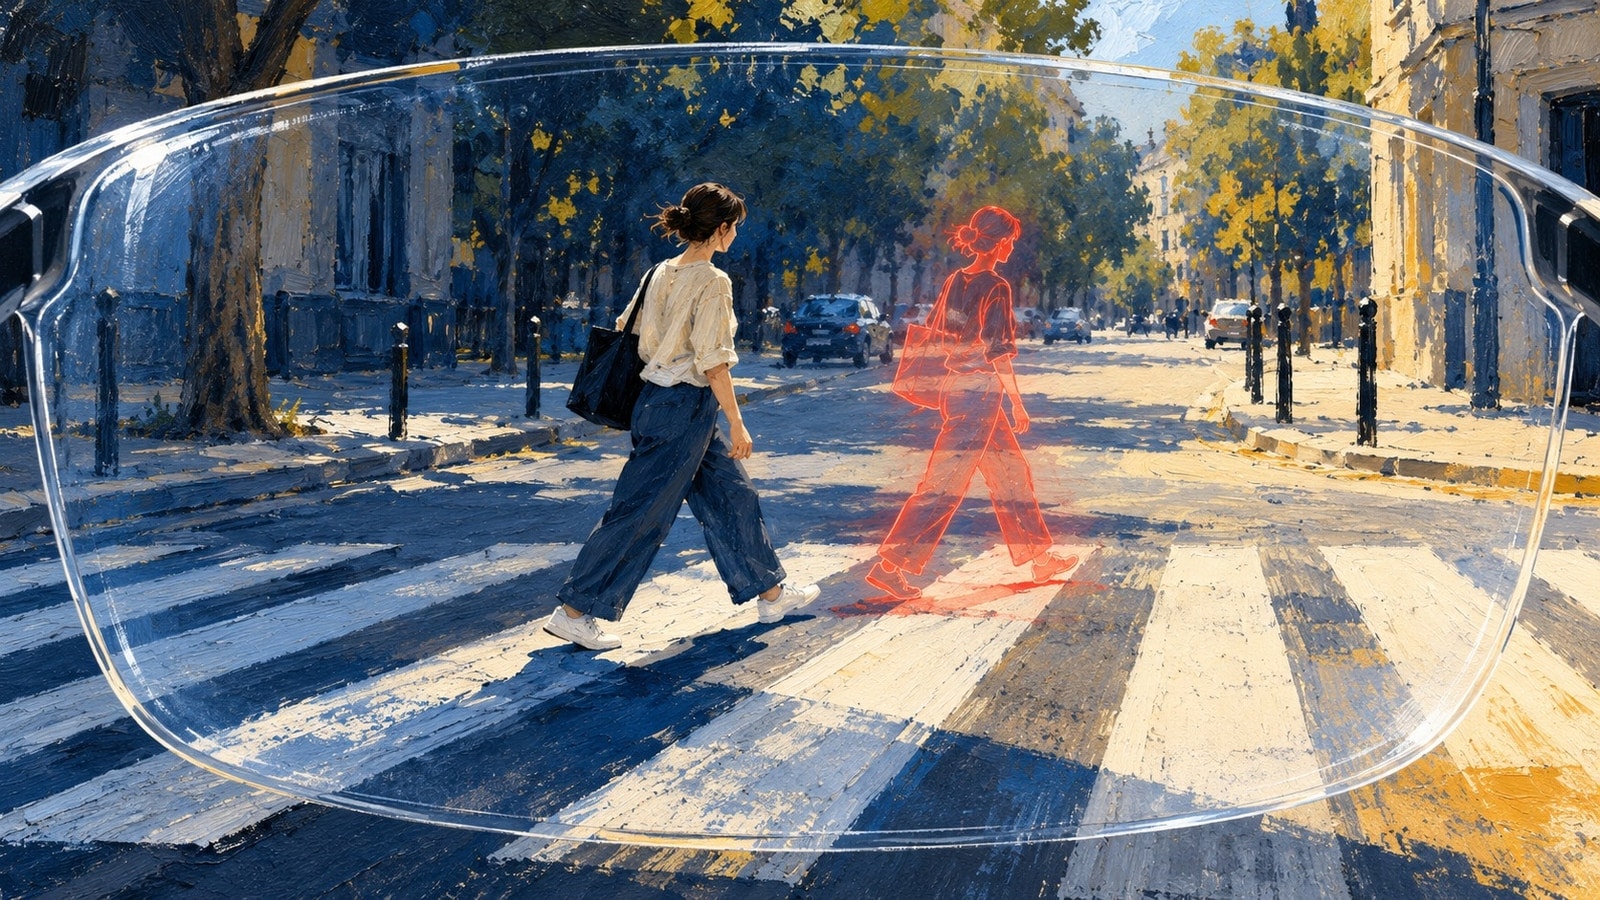
Imagine entering a station and seeing three people outlined before you have consciously decided where to look. One outline carries a warning. Another supplies a name. A third quietly disappears because the software considers it irrelevant. The interface feels like better vision. It is also an editorial system, choosing what deserves your attention and supplying an interpretation before you have assembled your own.
False Normal depicts augmented perception through peripheral labels and threat weighting. That is the manuscript's anchor for this article, not a prediction that its implants are about to arrive. The real question already applies to augmented reality, assisted inspection, and machine-generated alerts: what happens when a probabilistic judgment occupies the same visual space as the thing being judged? Cyberdelia's concern is the politics of attention at the interface, where an uncertain model can acquire the apparent solidity of an object.
A label is unusually persuasive when it seems attached to the world. A sentence on a separate dashboard invites some distance between the viewer and the claim. A marker placed directly over a doorway or face borrows the authority of location. The placement is a useful interface technique, but it can conceal several transformations. A camera produced an image; software selected features; a model generated a score; a threshold turned that score into a category; the display pinned the category somewhere. None of those steps is identical to seeing a property that exists in the scene.
Research on augmented reality decision support has examined precisely this danger. A study titled Fast and Accurate, but Sometimes Too Compelling investigates automation bias in AR support. Its relevance here is narrow: helpful visual assistance can also shape mistakes when people follow it. It does not establish that every AR system creates the same effect. The interface, task, reliability, and user all matter. The engineering lesson is to test behavior under wrong suggestions, rather than counting only the time saved when the suggestion is right.
Consider a maintenance worker inspecting a panel. Highlighting a likely loose connection can be valuable. If the marker also suppresses nearby information, the worker may stop searching too soon. The defect might be elsewhere, or the highlighted connection might be a symptom of a different failure. A good assistance system should help the worker investigate. A bad one turns the inspection into a confirmation exercise, with the user providing the final human gesture for a conclusion already chosen upstream.
The tempting remedy is a confidence number. Put 82 percent next to the outline and declare the problem solved. But a confidence score needs a meaning before it deserves that precision. Does it represent a calibrated probability for this task and environment? A classification score? Agreement between repeated runs? Even a well-calibrated model can perform differently under conditions absent from its evaluation. A precise-looking number can become another source of misplaced confidence if the user cannot tell which uncertainty it describes.
Uncertainty should change the interface's behavior, not merely its typography. A proposed design would make a tentative interpretation less visually dominant, reveal the observation that produced it, and make alternative explanations easy to inspect. When the system cannot localize an object reliably, it should avoid an exact outline that implies otherwise. When a reading is stale, the display should show that age at the point of use. These are design recommendations, not claims that a single visual convention can solve automation bias.
The system also needs a vocabulary for absence. No warning can mean no hazard detected, no data available, a sensor blocked, or the model failing to run. Those states are operationally different. If the display renders all of them as a calm scene, a loss of instrumentation masquerades as a safe environment. A technician should not need to open a diagnostic menu to discover that an apparently reassuring overlay has stopped observing the world.
There is a deeper feedback problem. A user learns where to look from the system. The system may then learn from the user's selections. Repeated use can make a preference look like independent confirmation, especially when the training record fails to distinguish unaided judgments from judgments made after a recommendation. Research on human–AI feedback loops has explored how interaction can amplify biases in human judgment. For product teams, the useful question is whether the data used to improve the system still contains independent information.
Threat labels raise the stakes further because they can alter an encounter. A person shown as dangerous may receive closer scrutiny. That scrutiny generates more observations, which can become more reasons for scrutiny. The interface is participating in the production of its future evidence. This is an inference about a possible deployment pattern, not a report that a particular system does it. A responsible evaluation would look for such effects rather than treating every later observation as an unbiased test of the original warning.
An assistance product should therefore preserve a route to ordinary observation. Users need to compare the scene with and without the interpretation, inspect the provenance of a label, and challenge it without disabling every useful function. That route must be practical during the actual task. A control buried in settings is unlikely to help somebody carrying equipment or making a time-sensitive judgment. Override behavior also deserves testing: can a user disagree safely, and does the system remember disagreement as disagreement rather than as training approval?
The performance metric should include recovery from error. Teams can seed incorrect, delayed, and ambiguous cues into controlled evaluations and observe whether users notice them, seek other evidence, and revise their decisions. An interface that is fast under perfect assistance but difficult to question under faulty assistance has a fragile success story. Evaluation should also compare the aided workflow with an unaided baseline. Otherwise the product may take credit for judgments users could already make reliably.
Augmentation changes more than how much information reaches a person. It changes the order in which observation and interpretation arrive. The desirable system makes that order visible and negotiable. The dangerous one makes a prediction feel like an additional sense, then asks the wearer to forget that somebody designed its priorities. Better perception should include a better ability to notice when the interpretation is wrong.
Visual overlays can make model predictions feel like properties of the world. Useful augmentation must preserve uncertainty, disagreement and ordinary observation.
Nine technologies behind False Normal
Independent technical essays inspired by manuscript concepts. No plot recap or ending reveals.
- The Implant Outlives the Company. Who Keeps the Body Working?
- A Scanner Finds a Match. The Institution Invents the Rest.
- The Person Watching Your Vitals Should Not Automatically Own Your Day
- When Your Eyes Come With a Ranking System
- A Perfect Hash Can Preserve a Perfect Lie
- The Air Gap Ends Where the File Begins
- An AI's Permission Slip Should Expire
- Two Timestamps Are Not Yet a Sequence of Events
- A Digital Tripwire Tells You Something Touched It. Now What?